AI Server Racks 2026: Vera Rubin NVL72, AMD Helios — Why Rack-Scale?
The deployment unit for AI servers is expanding from a single 8-GPU server to an entire rack. Rack power has risen from about 30 to 40 kW in the Hopper era to about 190 to 230 kW for Vera Rubin NVL72, and is heading toward about 600 kW for the 2027 Kyber rack. Interconnect, power delivery, liquid cooling and operations therefore have to be designed at the rack level. This article reviews the division of work between HGX, MGX and rack-scale platforms, the NVIDIA and AMD rack architectures, and 2026 progress from OEMs including Dell, HPE, Supermicro and Lenovo.
Key Takeaways
- Rack power: Industry analysis estimates about 120 to 140 kW for GB200 / GB300 NVL72, and about 190 to 230 kW for Vera Rubin NVL72; NVIDIA said at GTC 2025 that the 2027 Kyber rack will draw about 600 kW.
- Liquid cooling: Vera Rubin NVL72 is fully liquid-cooled with a 45°C coolant inlet temperature and fanless compute trays, reducing or eliminating the need for chillers.
- Power delivery: Rack power is moving from 54V DC busbars to 800 VDC; NVIDIA has published an 800 VDC rack roadmap at OCP, and Vertiv has introduced an 800 VDC MGX reference architecture.
- Open path: AMD Helios uses Meta's Open Rack Wide double-wide rack, with UALink over Ethernet for in-rack scale-up and Ultra Ethernet for scale-out.
- OEM progress: Dell delivered the first Vera Rubin NVL72 racks in June 2026, Supermicro began shipping in September, and HPE's Vera Rubin NVL72 is expected in December, with HPE also securing its first Helios deployment order.
Platform Form Overview
| Form | Representative platform | High-speed interconnect domain | Cooling | Deployment unit |
|---|---|---|---|---|
| 8-GPU server (HGX) | HGX B300, HGX Rubin NVL8 | 8 GPUs | Air or liquid | Single server |
| Modular server (MGX) | NVIDIA MGX reference architecture | By configuration | Air or liquid | Single server |
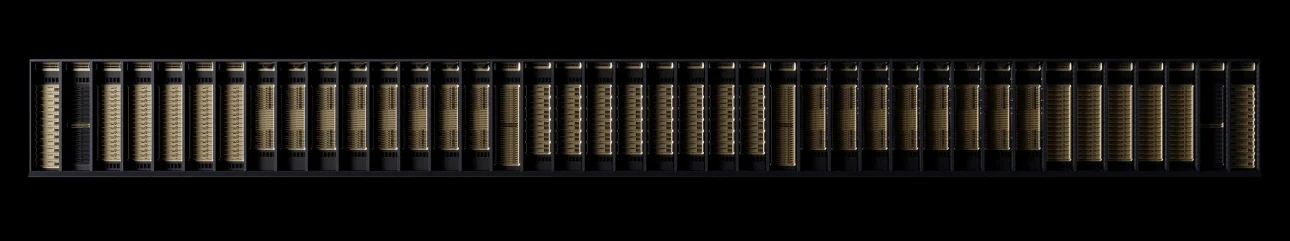
| NVL72 rack (Oberon) | GB200 NVL72, GB300 NVL72 | 72 GPUs | Liquid | Entire rack |
| NVL72 rack (third-generation MGX) | Vera Rubin NVL72 | 72 GPUs | Fully liquid-cooled, 45°C inlet | Entire rack |
| Kyber rack | Rubin Ultra (2027) | NVL144 to NVL576 | Fully liquid-cooled, 800 VDC power | Entire rack |
| Open Rack Wide double-wide rack | AMD Helios | 72 GPUs | Liquid, rear quick-disconnects | Entire rack |
When Synchronization Sets the Speed of a Job
Once a model outgrows a single machine, every added server also adds a communication boundary; scaling benefits depend on whether new compute outweighs synchronization waits.
Training and inference of large models require GPUs to exchange data repeatedly, wait for synchronization and then continue with the next step. If the added compute cannot outweigh the communication wait, scaling will not grow linearly with server count. The point of rack-scale design is to extend the high-speed interconnect domain from one server to an entire rack, so more GPUs work together within the same low-latency domain.
The 8-GPU server remains a practical design unit for mid-scale training, fine-tuning and inference. What sets rack-scale platforms apart is that they extend the coordination domain of interconnect, power, cooling and operations together, rather than simply placing more machines in a rack.
HGX, MGX and Rack-Scale: Three Different Layers
HGX, MGX and NVL72 answer questions at different layers; they are not mutually exclusive product choices.
- HGX: An 8-GPU accelerator baseboard that answers how a multi-GPU platform is assembled. OEMs build servers on it; for example, the Dell PowerEdge XE9780 is a 10U air-cooled version and the XE9780L a liquid-cooled version, both available with HGX B300.
- MGX: NVIDIA's modular server and rack reference architecture, letting OEMs combine different CPU, GPU and DPU configurations from standardized mechanical, power and cooling modules. Vera Rubin NVL72 uses the third-generation MGX rack architecture.
- Rack-scale systems: The entire rack is delivered and accepted as one product. NVIDIA says the MGX rack footprint used for GB300 NVL72 is also used for Vera Rubin NVL72 and Vera Rubin CPX, allowing data centers to reuse the same rack design.
The same platform name does not mean the same storage, networking or cooling design. For single systems, these differences can be checked unit by unit; for rack-scale deployments, they also involve a shared support scope and service unit.
Rack Power: From the 40 kW Class to 600 kW
Rack power rises sharply with every generation, making data center power and cooling capacity the first condition for deploying AI racks.
| Generation | Years | Power per rack (industry estimates) |
|---|---|---|
| Hopper (racks of 8-GPU servers) | 2023 to 2024 | About 30 to 40 kW |
| GB200 / GB300 NVL72 | 2024 to 2025 | About 120 to 140 kW |
| Vera Rubin NVL72 | 2026 | About 190 to 230 kW |
| Rubin Ultra Kyber | 2027 | About 600 kW |
A conventional enterprise rack typically draws only 5 to 15 kW, and even aggressive airflow engineering takes air-cooled racks to only about 40 kW. NVIDIA adds dynamic rack-scale power steering and Intelligent Power Smoothing with in-rack energy storage to Vera Rubin NVL72 to smooth load fluctuations; NVIDIA says its DSX MaxLPS lets operators deploy up to 40% more GPUs within the same power budget.
Power Delivery: From 54V Busbars to 800 VDC
Rising rack power strains AC distribution and low-voltage busbars through copper use and losses, and power architecture is shifting to 800 VDC.
Current NVL72 racks mostly use rack-level power shelves. In the Dell PowerEdge XE9712 (GB300 NVL72), for example, the 48U IR9048 rack follows the OCP Open Rack v3 design, using 33 kW power shelves to convert AC to 54V DC and feed it through the rack busbar, eliminating traditional PDUs.
NVIDIA's next step is 800 VDC: distributing 800V direct current from the facility straight to the rack. Compared with 415 / 480V three-phase AC, the same copper conductors can carry more than 150% additional power. The Vera Rubin NVL72 rack NVIDIA presented at Hot Chips 2026 uses 800 VDC, a liquid-cooled busbar, a retimer-free copper scale-up fabric and hot-swappable, cable-free trays; the 2027 Kyber rack is built entirely around 800 VDC. Vertiv has introduced an 800 VDC MGX reference architecture, and HPE has announced support for Kyber.
Liquid Cooling: 45°C Warm Water and CDUs
Liquid cooling has moved from an option to a prerequisite for rack-scale platforms; higher inlet temperatures let data centers reduce or even eliminate chillers.
Vera Rubin NVL72 is fully liquid-cooled, with fanless compute trays and a 45°C coolant inlet temperature. The higher inlet temperature widens the difference between the cooling loop and outdoor ambient conditions, so in many regions heat can be rejected with cooling towers alone, leaving more of the power budget for compute.
The liquid-cooling system extends from the chip to the facility: cold plates, manifolds, hoses, rack power shelves, coolant distribution units (CDUs), rear-door heat exchangers and facility cooling towers. CDUs come in in-row, in-rack and liquid-to-air sidecar forms. Supermicro's DLC-2 solution covers the full loop from cold plate to cooling tower with CDUs of up to 1.8 MW, and Lenovo is extending its Neptune liquid cooling to the Rubin platform.
Before deployment, confirm the facility's supply and return temperatures and flow rates, heat-exchange capacity, leak monitoring and the division of maintenance responsibilities.
Scale-Up and Scale-Out: NVLink, UALink and Ethernet
In-rack scale-up interconnect and between-rack scale-out networking are two separate design problems, each with proprietary and open paths.
| Layer | NVIDIA path | Open-standard path |
|---|---|---|
| Scale-up (GPU interconnect within the rack) | NVLink and NVLink Switch | UALink; UALink over Ethernet (UALoE) |
| Scale-out (between racks) | InfiniBand, Spectrum-X Ethernet | Ultra Ethernet (UEC), RoCE |
The UALink Consortium released the UALink 1.0 specification in April 2025, connecting up to 1,024 accelerators at 200G per lane; the Ultra Ethernet Consortium released its 1.0 specification in June 2025 for large-scale Ethernet transport in AI and HPC.
Nominal link speed is only a starting point. Software communication patterns, congestion control and network topology all affect effective throughput. Application testing should observe synchronization wait time and recovery after failures, not just link specifications. For the interconnect bandwidth of each GPU platform, see Enterprise AI GPUs 2026.
AMD Helios: The Open Rack Path
AMD Helios builds a rack-scale system from open standards, offering a second path alongside NVIDIA's MGX racks.
- Mechanical: Uses the Open Rack Wide (ORW) double-wide rack specification that Meta submitted to OCP, with rear quick-disconnect liquid cooling for easier servicing.
- Composition: Each rack has 72 AMD Instinct MI455X GPUs paired with 6th Gen EPYC "Venice" CPUs, Pensando Vulcano AI NICs and Salina DPUs.
- Scale-up: UALink over Ethernet connects the 72 GPUs, with AMD citing 260 TB/s of aggregate bandwidth.
- Scale-out: Each GPU has three 800G Vulcano NICs, or 2.4 Tb/s per GPU, supporting Ultra Ethernet transport; rack-level scale-out bandwidth is 43 TB/s.
HPE has introduced the Juniper Networking QFX5252 scale-up Ethernet switch for Helios, built on Broadcom's Tomahawk 6 silicon with six switch trays per rack, and secured its first Helios deployment order in September 2026. OpenAI, Meta, Oracle, Microsoft and Anthropic have all announced Helios adoption.
OEM and ODM Rack Platforms
| Vendor | Platform | Architecture | 2026 progress |
|---|---|---|---|
| Dell | PowerEdge XE9712 | GB300 NVL72, 48U ORv3 rack | Shipping |
| Dell | PowerEdge XE9812 | Vera Rubin NVL72 | Shipping First delivery to CoreWeave in June 2026 |
| Dell | PowerEdge XE8812 | Vera Rubin NVL4, 144 GPUs per rack, for HPC | Announced Expected early 2027 |
| Dell | PowerEdge XE9780 / XE9780L | HGX B300 8-GPU, air / liquid cooled | Shipping |
| Supermicro | Vera Rubin NVL72 rack | Vera Rubin NVL72, DLC-2 liquid cooling | Shipping Since September 2026 |
| HPE | Vera Rubin NVL72 by HPE | Vera Rubin NVL72 | Announced Expected December 2026 |
| HPE | AMD Helios AI Rack by HPE | AMD Helios, UALoE scale-up | Announced First deployment order |
| Lenovo | Neptune liquid-cooled Rubin platform | Vera Rubin | Announced |
Rack-level system manufacturing is carried out mainly by Taiwanese ODMs, including Foxconn, Quanta and Wistron. OEMs differ mainly in how much liquid-cooling and facility equipment they integrate, the extent of factory pre-integration and testing, deployment services and management software.
Operations and Failure Scope
The more integrated the rack, the larger the scope of work affected when a shared component stops; redundancy should match service objectives.
When replacing a compute tray, switch tray or power shelf, the downtime scope should be determined in advance: which component stopping affects which group of jobs. Redundancy in power, networking and cooling should match service objectives, so that a shared component does not become a single-point limit for the entire coordination domain.
For validation, test the full path from data ingestion, CPU preprocessing and GPU execution to cross-node synchronization and checkpoint writes. Stabilize one path first, then expand concurrency and node count. This approach turns rack design into measurable service capacity rather than just a larger hardware list.
Evaluation Framework
| Dimension | Metrics |
|---|---|
| Facility power | Power ceiling per rack, distribution method (AC or 800 VDC), redundancy level |
| Cooling | Inlet temperature and flow rate, CDU capacity, need for chillers, leak monitoring |
| Structure | Rack weight and floor loading, rack dimensions (standard or double-wide) |
| Interconnect | Scale-up domain, scale-out topology and congestion control, synchronization wait time |
| Service performance | Tokens produced per megawatt, time to first token, recovery time after failures |
| Operations | Hot-swappable trays, downtime scope, maintenance responsibility boundaries, deployment time |
FAQ
- How do HGX and MGX differ?
- HGX is an 8-GPU accelerator baseboard that defines how a multi-GPU platform is assembled; MGX is a modular server and rack reference architecture that lets OEMs combine different configurations from standard modules. Vera Rubin NVL72 uses the third-generation MGX rack architecture.
- How much power does a Vera Rubin NVL72 rack need?
- Industry analysis estimates about 190 to 230 kW, up from about 120 to 140 kW for GB200 / GB300 NVL72. NVIDIA said at GTC 2025 that the 2027 Kyber rack will draw about 600 kW.
- Why do AI racks need liquid cooling?
- Air-cooled racks can handle only about 40 kW, while NVL72 racks already exceed 120 kW. Vera Rubin NVL72 is fully liquid-cooled with a 45°C inlet and fanless compute trays, reducing or eliminating the need for chillers.
- How does AMD Helios differ from NVIDIA NVL72?
- Both use 72 GPUs per rack. Helios uses an Open Rack Wide double-wide rack with UALink over Ethernet for scale-up and Ultra Ethernet for scale-out; NVIDIA NVL72 uses an MGX rack with NVLink for scale-up and InfiniBand or Spectrum-X for scale-out.
Further Reading
- AI GPUs 2026: H200 to Vera Rubin — Why More Isn't Always Faster
- PCIe Gen6 SSDs 2026: Can Micron 9650 and PM1763 Cut GPU Wait?
- Balanced Server Design 2026: Every Part Upgraded — Why No Faster?
Sources
- NVIDIA Technical Blog: Vera Rubin NVL72 Rack Design
- NVIDIA: OCP, 800 VDC and Kyber
- ServeTheHome: Vera Rubin NVL72 Rack at Hot Chips 2026
- SemiAnalysis: Vera Rubin Rack Power and Cooling
- ModuleEdge: Rack Power Roadmap and 800 VDC
- NVIDIA Vera Rubin NVL72
- NVIDIA MGX
- Dell PowerEdge XE9712 Spec Sheet
- Dell: First Vera Rubin NVL72 Rack Delivery
- iTWire: Dell XE8812, HPE and Lenovo Rubin Platforms
- Supermicro Vera Rubin NVL72 Shipments and DLC-2
- AMD and HPE: Helios Open Rack
- Fierce Network: Helios UALoE and Ultra Ethernet
- Converge Digest: Helios and Open Rack Wide
- HPE: First Helios Deployment and QFX5252 Switch
- Silicon Report: Vera Rubin ODMs and Shipment Timeline
- UALink Consortium Technical Resources
Last updated: 2026-10-01